Datacoves Airflow Decorators
With the introduction of the task flow API in Airflow we have released the Datacoves decorators to make writing DAGs simple!
While the Datacoves decorators are recommended, the Datacoves Operators are still supported.
Decorators
@task.datacoves_bash
This custom decorator is an extension of Airflow's default @task decorator and should be used to run bash commands, pull secrets etc.
The operator does the following:
- Copies the entire Datacoves repo to a temporary directory, to avoid read-only errors when running
bash_command. - Activates the Datacoves Airflow virtualenv.
- Runs the command in the repository root (or a passed
cwd, relative path from repo root where to run command from).
Params:
env: Pass in a dictionary of variables. eg"my_var": "{{ var.value.my_var }}".
Please use{{ var.value.my_var }}syntax to avoid parsing every 30 seconds.outlets: Used to connect a task to an object in datahub or update a datasetappend_env: Add env vars to existing ones likeDATACOVES__DBT_HOME
def my_bash_dag():
    @task.datacoves_bash
    def echo_hello_world() -> str:
        return "Hello World!"
dag = my_bash_dag()
@task.datacoves_dbt
This custom decorator is an extension of the @task decorator and simplifies running dbt commands within Airflow.
The operator does the following:
- Copies the entire Datacoves repo to a temporary directory, to avoid read-only errors when running
bash_command. - It always activates the Datacoves Airflow virtualenv.
- If
dbt_packagesisn't found, it'll rundbt depsbefore the desired command. - It runs dbt commands inside the dbt Project Root, not the Repository root.
Params:
Datacoves dbt decorator supports all the Datacoves dbt Operator params plus:
connection_id: This is the service connection which is automatically added to airflow if you selectAirflow Connectionas theDelivery Mode.
dbt profile generation
With the connection_id mentioned above, we create a temporary dbt profile (it only exists at runtime inside the Airflow DAG's worker).
By default:
- Connection details (user, password, warehouse, database, schema, role, etc.) come from the selected service connection (
connection_id). - Profile name comes from the Profile name field in Project or Environment settings. It must match the
profile:value in yourdbt_project.yml. - Target name is
default.
These can be overridden with the following params:
| What | How |
|---|---|
| Target name | target: the target name this temporary dbt profile will receive |
| Connection details | overrides: a dictionary of dbt profile fields to override, such as warehouse, role, database, schema, etc. |
For Snowflake and Databricks connections, a schema must be set, either in the connection's Schema field or via overrides. Leaving it empty causes an error like:
Credentials in profile "my_dw_profile", target "default" invalid: None is not of type 'string'
The Airflow Snowflake provider docs list schema as optional. That applies to the Airflow connection, not to the dbt profile generated from it, which requires schema.
Basic example:
def my_dbt_dag():
    @task.datacoves_dbt(
      connection_id="main"
    )
    def dbt_test() -> str:
        return "dbt debug"

dag = my_dbt_dag()
Example with overrides:
def my_dbt_dag():
    @task.datacoves_dbt(
        connection_id="main",
        overrides={"warehouse": "my_custom_wh"},
        target="testing"
    )
    def dbt_test() -> str:
        return "dbt debug -t testing" # Make sure to pass `-t {target}` if you are using a custom target name.

dag = my_dbt_dag()
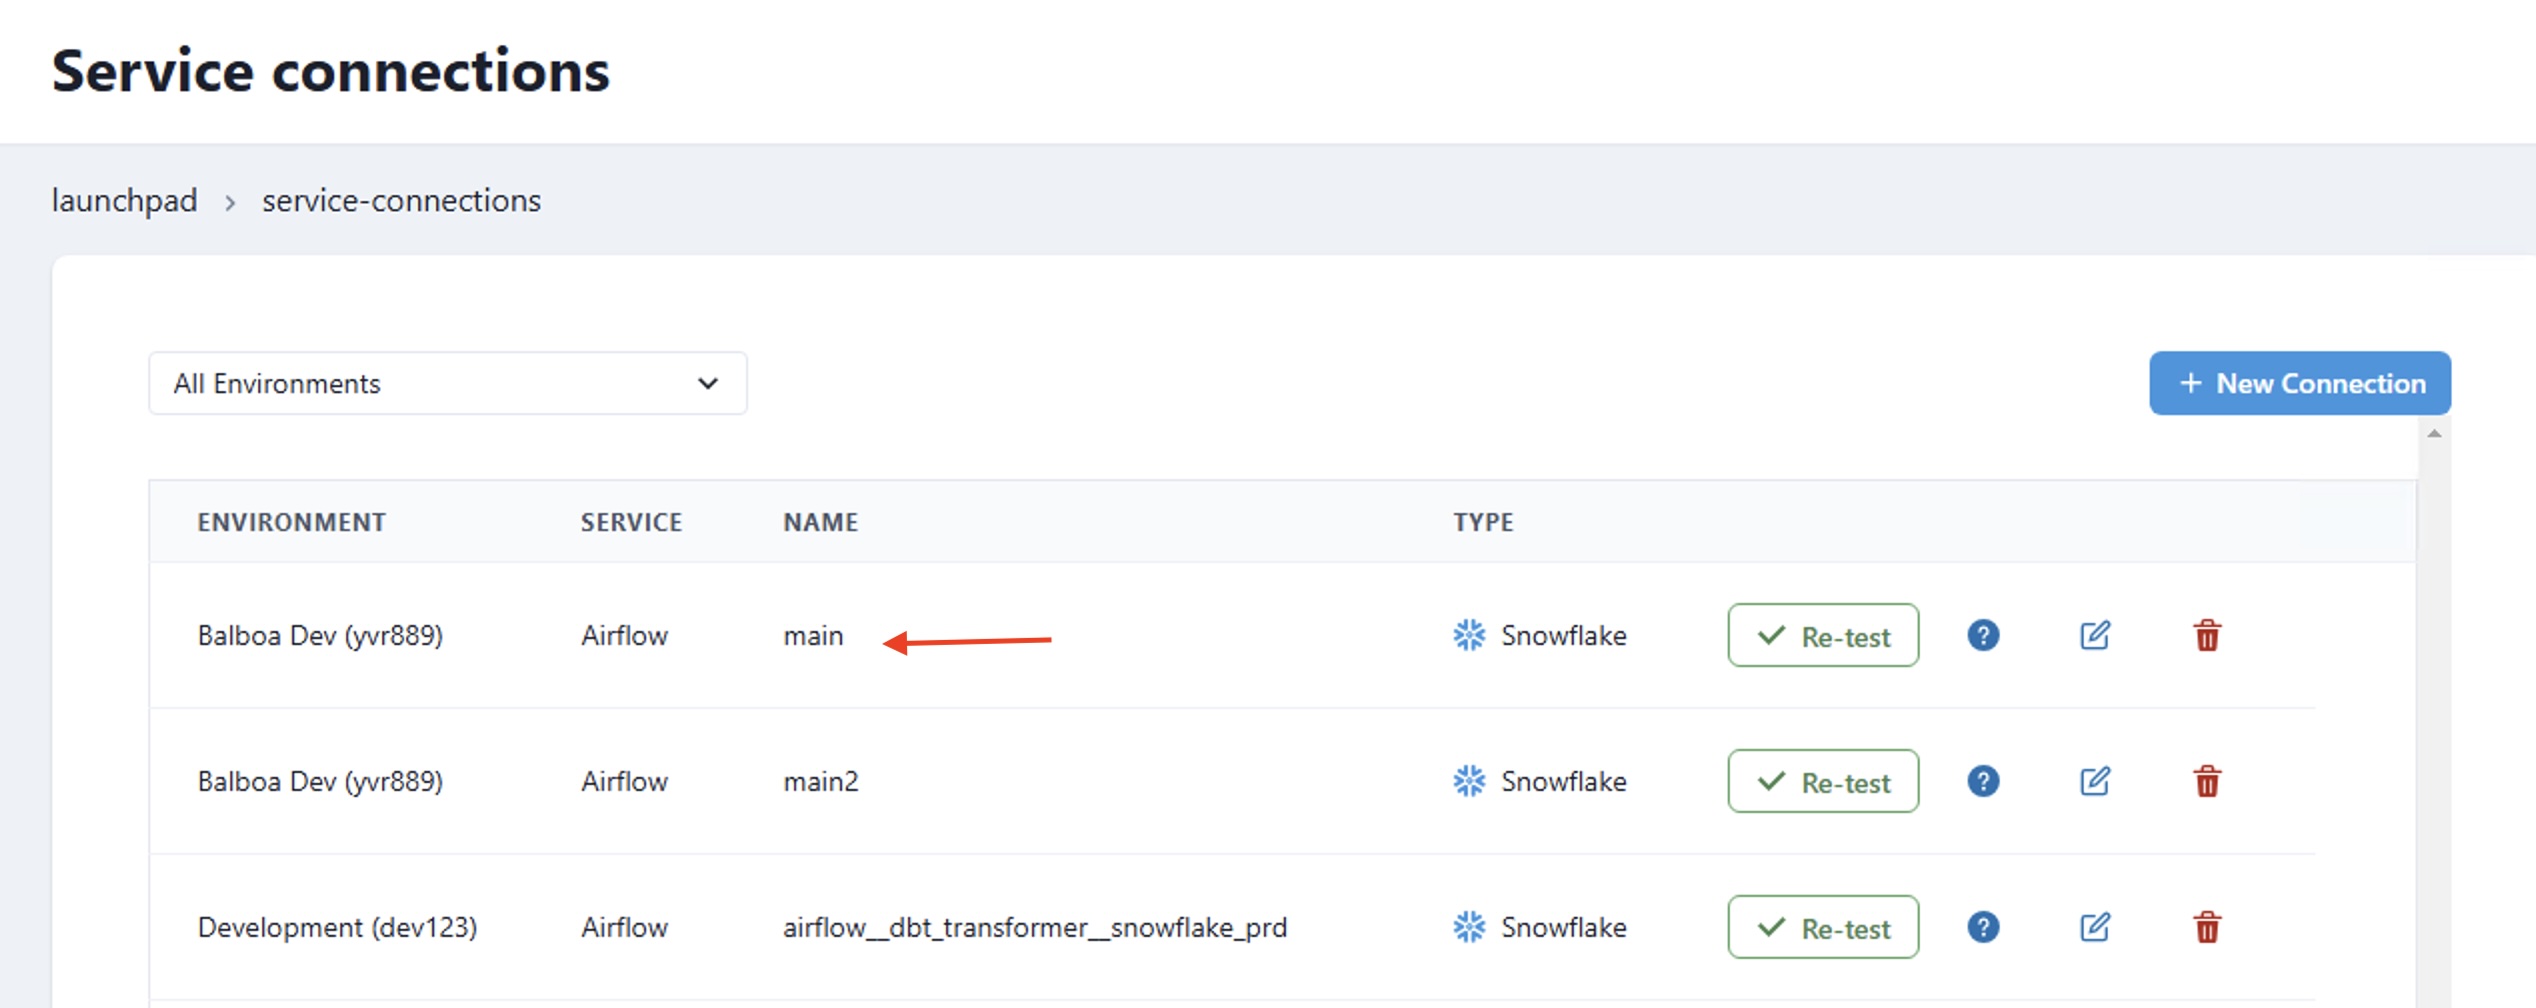
The examples above use the Airflow connection main which is added automatically from the Datacoves Service Connection.
Setting values dynamically
target and overrides support Airflow templating, so their values can be fixed or set dynamically. The examples below use schema, but the same works for any key in overrides and for target (except the last option):
| Option | Example overrides value |
|---|---|
| Fixed value | {"schema": "my_schema"} |
| Chosen when triggering the DAG | {"schema": "{{ params.schema }}"} |
| Per environment, from an Airflow Variable | {"schema": "{{ var.value.dbt_schema }}"} |
| From an environment variable, resolved by dbt | {"schema": "{% raw %}{{ env_var('DBT_SCHEMA') }}{% endraw %}"} |
Chosen when triggering the DAG: define a default in the DAG's params. When the DAG runs on its schedule, it uses the default. When you trigger it manually from the Airflow UI, Airflow asks for the value, pre-filled with the default, and you can change it before starting the run.
@dag(
    params={"schema": "my_default_schema"},
    # ...
)
def my_dbt_dag():
    @task.datacoves_dbt(
        connection_id="main",
        overrides={"schema": "{{ params.schema }}"}
    )
    def dbt_run() -> str:
        return "dbt run"

dag = my_dbt_dag()
Per environment, from an Airflow Variable: create an Airflow Variable (e.g. dbt_schema) in each environment with the value to use there.
From an environment variable, resolved by dbt: pass the environment variable with env and let dbt resolve it at runtime. This option only applies to overrides, since dbt resolves env_var inside the profile's connection details, not in the target name.
@task.datacoves_dbt(
    connection_id="main",
    overrides={"schema": "{% raw %}{{ env_var('DBT_SCHEMA') }}{% endraw %}"},
    env={"DBT_SCHEMA": "my_schema"},
    append_env=True
)
def dbt_run() -> str:
    return "dbt run"
{% raw %}...{% endraw %}is required. Without it, Airflow tries to renderenv_varitself and the task fails with'env_var' is undefined.append_env=Truekeeps the rest of the worker's environment variables. Without it, only the variables inenvare available to the task.
Uploading and downloading dbt results
From Datacoves 3.4 onwards, the datacoves_dbt decorator allows users to upload and download dbt execution results and metadata to our dbt API.
dbt-API is a feature that is not enabled by default. Please contact support for further assistance.
This is particularly useful for performing dbt retries.
The new datacoves_dbt parameters are:
dbt_api_enabled(Default:False): Whether your Environment includes a dbt API instance.download_static_artifacts(Default:True): Whether user wants to download dbt static artifact files.upload_static_artifacts(Default:False): Whether user wants to upload dbt static files.download_additional_files(Default:[]): A list of extra paths the user wants to download.upload_additional_files(Default:[]): A list of extra paths the user wants to upload.upload_tag(Default: DAGrun_id): The tag/label the files will be uploaded with.upload_run_results(Default:True): Whether therun_results.jsondbt file will be uploaded.download_run_results(Default:False): Whether therun_results.jsondbt file will be downloaded.upload_sources_json(Default:True): Whether thesources.jsondbt file will be uploaded.download_sources_json(Default:False): Whether thesources.jsondbt file will be downloaded.
Static Artifacts
The static artifacts are important dbt-generated files that help with dbt's operations:
target/graph_summary.json: Contains a summary of the DAG structure of your dbt project.target/graph.gpickle: A serialized Python networkx graph object representing your dbt project's dependency graph.target/partial_parse.msgpack: Used by dbt to speed up subsequent runs by storing parsed information.target/semantic_manifest.json: Contains semantic information about your dbt project.
These files are downloaded by default (when download_static_artifacts=True) and are tagged as "latest" when uploaded.
@task.datacoves_airflow_db_sync
The following Airflow tables are synced by default: ab_permission, ab_role, ab_user, dag, dag_run, dag_tag, import_error, job, task_fail, task_instance.
Params:
db_type: The data warehouse you are using. Currently supportsredshiftorsnowflake.destination_schema: The destination schema where the Airflow tables will end up. By default, the schema will be named as follows:airflow-{datacoves environment slug}, for exampleairflow-qwe123.connection_id: The name of your Airflow service connection which is automatically added to airflow if you selectAirflow Connectionas theDelivery Mode.additional_tables: A list of additional tables you would want to add to the default set.tables: A list of tables to override the default ones from above. Warning: An empty list[]will perform a full-database sync.
def airflow_data_sync():
    @task.datacoves_airflow_db_sync(
        db_type="snowflake",
        destination_schema="airflow_dev",
        connection_id="load_airflow",
        # additional_tables=["additional_table_1", "additional_table_2"]
    )

dag = airflow_data_sync()